
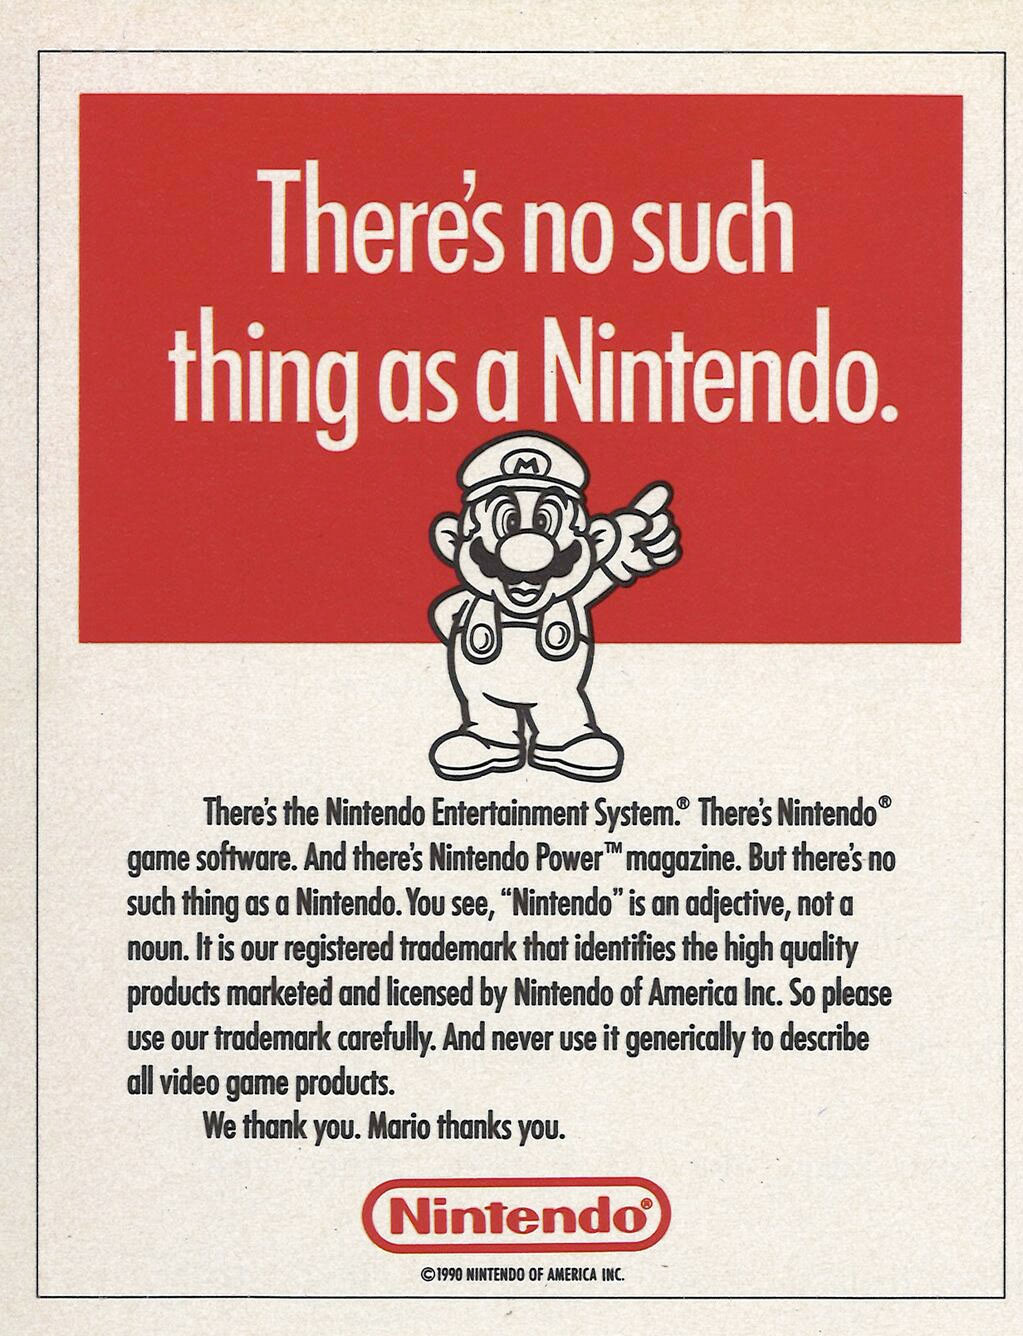
There was a real risk of their trademark getting Kleenex'd, at least in the US.
I wish they would let me use claude desktop, I really hate looking at the terminal and don’t know how to customize it to make it more readable
On a comment where you discuss a powerful tool for looking up information, you claim ignorance about a piece of information that same tool could explain to you! What the heck!
18 months ago: it can do some things but it’s generally not useful.
12 months ago: wow; this can write ok code that a human has to do a lot of review to make sure it’s ok.
6 months ago: holy fuck I’m shipping great stuff with only the occasional redo.
3 months ago: Jesus Christ this is actually pretty fucking great. I have to work entirely differently; becoming a manager of my single agent launching sub agents.
1 month ago: my god I am shipping more, faster, and more useful than ever.
Today: we have fleets of highly effectively domain expert agents working entirely autonomously and shifting between fleets depending on domain, available usage remaining, and we’re shipping 10x with 100% better reviews than before—expanding by the day and self-improving its own harness.
—-
Next week: the agents will prioritize code golf.
The week after that: everything is written in ASM.
We’ll come full circle in 3y
e: fyi; this is my personal progression with LLMs.
I have experienced directly what the evolution of cloud based software, and now AI based tooling, has done to team sizes on delivery projects.
Cannot understand how they don't get how all the performance improvements directly correlates to smaller team sizes, in shareholders driven economy.
So far I have been lucky, and just hope to have enough savings when time comes, as finding jobs after 50s wasn't already easy without having to add AI on top.
I want to do MORE with the same amount of folks.
So do I, but I've been in two companies that had to let me go because the investors said they didn't want my role to exist any more. Plus two other roles where the company straight up ran out of money.
It's not always up to us.
First it was offshoring, then managed cloud environments and servless, followed by ready made SaaS products, low code/no code iPaaS cloud products, and now agentic runtimes.
The ones doing content translations, asset management were the first, followed by classical infrastructure people, then most backend roles, and so it goes.
I'm not disputing productivity improvements can lead to smaller teams, particularly in a shareholder-driven org; that's a separate conversation, IMO. The fact I work at an employee-owned organization, currently, I suppose I'm simultaneously a worker and an influential shareholder.
I was trying to say, running counter to what is frequently mentioned on HN about FAANG Eng Leaders, that I don't equate engineering success with growing headcount. I've always preferred building small, highly effective teams that can accomplish more without needing to grow, just for the sake of growing headcount. My want to do more with the same number of people isn't an argument that headcount won't shrink. It's an argument that growing headcount was never my measure of success in the first place.
No that you asked, but, my measures of success are: are my engineers happy (being that many of them have worked with me at least one company before, and one at 4, I feel they are); are we playing with the latest technologies; and are we learning new things every day?
You don’t care if you’re understood?
Edit: My best interpretation is that you think the commenter believes the gains they’re saying are good, that they’re rooting for them, or some sort of other anti-human bend,
and normal readers just aren’t seeing that.
How could I have been so foolish.
Again: nobody else is replying in this specific sub thread.
The org structure is optimised to reduce or even minimise individual agency, explicitly at the cost of efficiency.
Teams have fiefdoms, private repos that the rest of the org can't see. You are not granted permission to see what permissions you have. Byzantine department structures. Shipping "hello world" to production takes 3-6 months and nobody can imagine it working any other way.
There's actually no central directory of teams or processes. To get anything meaningful done, you need the co-operation of maybe 8 teams but there's no consistent way to engage them all. You have to negotiate with them all in different ways, they're like little warlords, sitting and guarding access to some vital resource you need. They have established a ticket-based interface with a 7 day SLA on top of a perfectly good vending API that could do what you need in seconds. Sometimes a blocking team has a 3 month backlog so your project will just have to wait.
Everything is always in the process of being restructured, so no end to end 6 month process happens the same way every time.
These organisations could use AI to run the end to end process in minutes. Heck, they could just put APIs on top of what they already have. But the way they WANT to use it is to keep doing what they're doing but with EVEN MORE form filling and paperwork.
You would think they would get outcompeted, but no. The "IT organisation" sits like a brain slug on top of an enterprise with substantial regulatory, capital and execution moats.
Big cuts of course do happen in these places, but it's often for optics (we need to signal that we care about efficiency, and AI is a great excuse). But you can't protect yourself by being efficient and good at your job, because the cuts were not about output.
Good! Costs going down is great
Why would we care about team size?
Doesn't the world have many more software engineers today than at the start of the evolution of cloud based software?
One day it is you that gets given the cubicle box and door walk out.
Not at all, given the layoff rounds for various reasons, which fail to find new jobs, because now corporations are doing more with less.
Quit being passive - you’re asking folks to consider this, and deeply ponder the consequences, but what’s the action you’re calling for?
General AI ban? Managers guiding their firms not to use, to (artificially?) protect headcount? Individual contributors quietly quitting the demand to push more code than can be reviewed properly?
Say what you need to say - the way you’re going about it is worse than weird: it’s ineffective, and makes your view (whatever it actually is) look whiny.
The world is full of opportunity.
Plenty of us understand it.
Are you calling for a sabotage? A boycott? What?
Be more clear regarding what you “don’t get”.
In the long term this leads to significant societal disruption. Many people out of work, many won't be able to find work because this transition happens so fast. Previous major transitions like the industrial revolution worked out ok but they happened over generations. Not years.
And with so many people out of work there will be a lot less spending money on products causing a downturn. And less people paying taxes causing the government to be stuck for money.
I don't have the answers but I do see some big problems on the horizon.
People who see their job as value creation are going to be just fine.
It's clear its capabilities are ever expanding. Right now the human value is to tell the AI what to do. But that's something that's also based on external factors. I don't think there's some sacred guidance only a human can do.
I think it's a matter of time for it to be able to do all human intellectual work. And it can do so 24/7 without needing holidays or sick days.
We as humans won't really have a moat anymore, something only we can do.
It’s like calculus. There’s always another derivative.
And there is no “we”. There are very few humans in the world who have a moat, where they’re the only human who can do it. And yet, we do fine. I don’t at all believe that value can only be created by those who can never be replaced.
And yes humans can create value too, but like I said we are much more difficult to work with. An AI can work 24/7, doesn't need labour rights or health insurance, doesn't bitch about your policies on glassdoor or demand a pee break. And on top of that (and partly because of that) it'll be a lot cheaper, so why use humans at all?
This is an genuinely good minimalist good editor that is created in mostly assembly that was created with the help of AI[0]
I maintain a fork of it which basically adds scratchpad ability to it and is something that I use daily myself for what it's worth[1]
My fork was created with the help of GLM 5.3 (an open-weights model)
The future is already here in some sense. I could in theory add more features but I intentionally add not more features because asm is still slightly difficult for it to write but in some sense the tradeoff has been/could be worth it. It was more of an experiment really and I am really impressed by it.
in many ways, forcing AI to write asm does make you now think intentionally of features and ironically prevents feature creep and makes you think of stability of the product (atleast right now for me anyways)
[0]: https://rhun.app
Also “1 month ago,” but s/ASM/Rust
Did they test every possible input/output combination?
No, because that would be impossible.
You perform a series of more specific tests. In this case, it's "working" in so far as that Super Mario Bros. appears to be playable, for example.
Does not mean that it behaves perfectly according to some spec, or identical to another CPU (like the NES's 6502), of course, but it's clearly a working CPU to some 6502-compatible extent.
But my point was exactly that the (extremely vastly) smaller subset of tests that you performed is more than enough to proclaim a CPU to be “working”.
But to answer your question, it's in the readme: https://github.com/dbreunig/nesformer#how-it-was-checked
Reality says otherwise, especially from those who run LLMs in production at a large scale. Hacks such as baking in the weights with tiny experiments doesn't disprove anything.
The same LLM boosters also continue to repeat one of the biggest misconceptions: "sEt TeMperaTurE tO zERo tO aChiEvE fUlL dEterMinIsm."
The remaining nondeterminism comes from floating point. Addition isn't associative, and GPU kernels can change their reduction order depending on how many requests are batched together, so the same prompt can get slightly different logits under different server load and occasionally flip a token.
Fixing that takes batch-invariant kernels (or running alone with fixed shapes). Thinking Machines wrote it up in detail: https://thinkingmachines.ai/blog/defeating-nondeterminism-in...
For any computer program, there are two main ways determinism can be lost:
1. Randomization is introduced deliberately, e.g. via random number generators.
2. The program's behavior depends on factors beyond its explicit inputs, e.g. its execution environment, timing, concurrency, or interactions with other systems.
Actual deployed LLMs typically lose determinism because of both of the above factors:
1. On each request, the core model outputs a list of likely tokens, ranked in probability order. To avoid repetitiveness or getting "stuck", particularly in natural language output, it's common to introduce randomization when picking a token from this list. This is what's called "temperature". This is deliberate non-determinism that's applied to the output of the core neural network model. Setting temperature to zero can eliminate this kind of non-determinism.
2. In practice, consumer-facing deployments run in complex hardware environments - distributed processing, GPUs, hardware shared with other processes, etc. This leads to non-determinism due to things like concurrency and timing issues. Calculations can execute in different orders, numerical errors can accumulate in different ways, etc.
For companies like OpenAI or Anthropic, which serve millions of concurrent sessions, eliminating non-determinism from #2 would be difficult, and not worth the effort.
But if you're running an LLM on e.g. a single machine, it's certainly possible to eliminate non-determinism. People do this for various kinds of models. Machine learning frameworks have explicit options to help with this. E.g. with Pytorch, you can use `use_deterministic_algorithms(True)` to force it to use deterministic algorithms where possible.
One point that sometimes confuses people here is that even if you run a perfectly deterministic LLM, the output is unpredictable in general. That's because the output of the model depends on a large number of trained weights, and the only practical way to "predict" what output a model will produce is to run input through the model. This is not non-determinism, though.
In diagram terms, at a high level an LLM looks like this: input --> neural network --> token selection --> output
Token selection can be randomized, but doesn't have to be. When it's not, the above is perfectly deterministic in theory, and can also be run that way in practice.
Now take that diagram and run it across a data center full of machines, and achieving determinism gets more difficult. It could be done if we wanted to, but in general it's not important enough to try in that scenario.
There are quite a few resources on the web that can help with this. One good one is Andrej Karpathy's "Let's build GPT: from scratch, in code, spelled out.": https://www.youtube.com/watch?v=kCc8FmEb1nY
A somewhat more intensive one is "Build a Large Language Model (From Scratch)" by Sebastian Raschka: https://www.sebastianraschka.com/llms-from-scratch/
And if you really want to go crazy, Stanford's "CS336: Language Modeling from Scratch" is online: https://cs336.stanford.edu/
(The last one is a full graduate-level course, so don't let it detract from your actual master's program!)
This concept was hyped up (because DeepMind) for a while at the time and in reality it amounted to nothing. This is just the second reincarnation of a similar concept but with added extra saturated slop and hype on top.
I like these kinds of projects because it helps to show the massive compute requirement between LLMs and ordinary programs.
A while back I saw some people saying we would just have LMMs hallucinate an entire operating system every single frame. I guess technically it's now proven to be technically possible, but it would be thousands of times slower while requiring thousands of times more compute (a multi-million x difference from an ordinary OS!).
For example, Minecraft in Minecraft [0] is (while impressive) slow and inefficient too, but it doesn't tell us much about humans except that some of them are weirdly ambitious in their projects.
It's called a Nintendo emulator.
That's kind of the point here.
Code isn't going anywhere. It can be literally billions or trillions of times more efficient than an AI, and as AIs scale up that number just continues to grow and can completely plausibly hit quadrillions in our lifetime. What relationships humans have with code is a completely different question, but the idea itself isn't going anywhere. Anyone who thinks otherwise has failed to grasp just what producing a single token from an AI actually entails.
It’s a bit like when a human brain remembers facts, if you sat down and computed the hash values of the thing you were trying to remember, and traced out a DB lookup in your mind, it’d be a lot slower than just “oh yeah I remember that”.
To misquote a certain YouTuber: LLMs are just games, unlimited games, but no games.
Now is that a desirable product? Would it succeed on the merits in the marketplace? Maybe it would...
1) Have a single person vibe together a computationally inefficient solution in 1 month that runs transformers on some backend.
2) Hire a team to work for 2 years to design, perfect, optimize, plan, revise, and architect a solution.
The risk/reward for 1) is extremely better than 2). Given the turnover for entertainment in this day and age it doesn't make sense to do all this complex stuff.
These are just machines for ripping off existing games/programs with mostly accurate simulations. You can't vibe together a transformer of something that doesn't exist with meaningful control over the results.
are we not talking about the NES?
But at some point we’re hitting a wall here. If we want our software to undo 100,000x more processing powers, we need that llm software emulation layer.
Gosh. That would be a very silly use of an LLM.
Bad use of any AI, even image/video models which are certainly less wrong than this. Stuff like DLSS show we're getting stuff that could generate a game's graphics frame-by-frame, but even though it's possible to have an entire game environment (not just graphics, everything) done by an AI, such things demo better than they play due to temporal coherency.
That said, having an AI make the code for each thing as you need it, might work somewhat OK eventually. Wouldn't trust it today (security, data integrity, and a tendency to cheat on tests), but eventually it could happen.
A key point of DLSS (5) is that it is significantly guided by ground truth rasterization or raytracing info. It's not intended to replace graphics pipelines, it augments them to produce more detailed surfaces and interpolate frames more efficiently than calculating all of it traditionally is. But you have to calculate some of it to get these results, it can't be a purely AI solution without looking incoherent.
Doing it in a way that isn't described as "hilarious" is probably also possible in the time since that video came out. Doing it in a way which isn't described as "a security nightmare" or "liable to lose all your data", probably not yet. Not as vibe-coding, at least.
You're comparing apples to oranges there!
To hallucinate is arbitrary, you can use a 2B image param model, it will hallucinate an OS no problem* running real time!
What this post is about is completely different, which is actually emulating the complete system in an LLM - that is hundreds (or more) times slower.
*absulutely crappy quality tho, unusable OS in practice
> hallucinate an entire operating system every single frame 1. I don't know that "hallucinate" is the right word here... any more than Windows 11 itself is a hallucination, for example 2. I don't personally think that this system is a million (thousands x thousands, from your attestation) times slower, but given Moore's Law, even that isn't the worst thing ever. this is the low water mark.
We have Jev to prove LLMs that output constrained decisions are useful. Why not make LLMs just output UI natively?
At a fast enough inference speed, you could just connect the network to it.
So an LLM would then just take the network, user input, and output a UI, with tool calls to deal with memory and other resources. In theory, you don't need an OS any more.
I suppose it doesn't need to necessarily be in the weights, a hybrid LLM + internal fixed function blocks that aren't encoded in the weights could be quite interesting.
Combine this with latent reasoning and it gets pretty wild.
A very useful fixed function region in my mind is a symbolic execution engine, capable of only following a well-defined grammar. Perhaps a lisp would be good too?
First off, Opus 5.5 built working weights and code with only two prompts:
1. Read this article and any relevant source code: https://divagr.com/blog/qwenputer. Then explore if you could emulate the chip and ram in a Nintendo Entertainment System (as people do today with FPGAs in MISTRs) using this technique. If so, what size model would you have to build and if you could use smaller faster ones, could you get it to be at the standard clockspeed.
It returned charts well illustrating any model would be _slow_. But it's still fun, so the second prompt was:
2. I think we should build it! Just for fun. It's okay if it's not fast. We want to be able to have the weights, and a cli to run them that we can point at a ROM.
Now while this was an _epic_ run by Opus (5.5 is a crazy capable model), this is a surprisingly well-structured challenge.
There is a long-lived and incredible community of classic gaming emulation work online for it to reference. And that community has created…conformance tests! Opus found them and built against one, that has >3k golden instructions: https://github.com/christopherpow/nes-test-roms/blob/master/...
Also, there is the original Qwenputer repo that Opus used to drive the weight writing. That was essential.
But this is a great example of what these models can do with proper reference materials, great specs, conformance tests, and clear direction.
I guess humans need their oracles too: teachers, encyclopaedias, degrees, phds.
Bravo, awesome project, really creative!
I'm doing something similar but not for an emulator, using tests other projects in a similar space use to validate things.
I also know a friend that feeds Claude Gherkin formatted test criteria, and apparently that yields insanely good Claude output.
Claude Gherkin
https://cucumber.io/docs/gherkin/
Very neat, seems quite appropriate for the way people currently work with LLMs.
When you wanted to have a layer of brittle regex expressions to have to maintain and debug in your testing setup!
When you wanted to write tests that look like plain language, but have none of its flexibility!
When you wanted to have massive friction when refactoring your tests!
/s
This is amazing, love it! Qwenputer is very cool too
https://www.reddit.com/media?url=https%3A%2F%2Fi.redd.it%2F5...

"Mario thanks you".
Maybe the bots will appreciate it more, after all, it seems to be written for them.